Table of Contents
- •What AI Content Agents Actually Are in 2026
- •Why Search Rankings Changed and Why Agents Are the Response
- •The Four Ranking Surfaces Agents Must Target
- •How AI Content Agents Improve Rankings - The Core Mechanisms
- •Staying Inside Google Policy - Helpful Content vs. Scaled Abuse
- •AI Content Agents vs. Traditional SEO Tools - A Direct Comparison
- •Building an Agentic Content Workflow from Day One
- •What Realistic ROI and Timeline Look Like
- •The Human Role in an AI-Agent Content Operation
- •Choosing the Right AI Content Agent for Your Operation
- •Where AI Content Agents and Search Rankings Are Headed
- •Frequently Asked Questions
The pitch is familiar by now. AI content agents, vendors say, will scale your content operation, close your topical gaps, and push your rankings up across the board. What the pitch rarely includes is a precise account of how that actually happens, which ranking surfaces benefit, where the approach breaks down, and what the realistic conditions for success look like.
That gap matters more in 2026 than it did even two years ago, because "ranking" now means at least two different things. A content strategy that earns position three in traditional blue-link results may simultaneously be absent from every AI-generated answer surface. A page cited frequently in Google AI Overviews may never appear on the first page of classical results. AI content agents sit at the intersection of these two environments, and understanding how they operate across both is the only way to evaluate whether deploying them is worth the investment, or whether you are about to spend budget producing content that performs on neither surface.
What follows is a practitioner-level account of what AI content agents actually do to search rankings in 2026, the mechanisms behind that effect, the deployment conditions that determine success, and the failure modes that most vendor pitches leave out.
What AI Content Agents Actually Are in 2026
An AI content agent is a software system that can autonomously plan, produce, optimize, and monitor content through a multi-step operational loop without requiring human instruction at each stage. The word "agent" is doing real definitional work here. An agent perceives its environment (the site's current content, the competitive gap, keyword data, search results), makes decisions, executes actions, and adjusts based on feedback. That cycle repeats without a human initiating each iteration.
This is categorically different from a content team using ChatGPT to speed up drafting. It is also different from a platform that runs automated keyword reports and waits for a human to act on them. An AI content agent acts on its own findings across the full content lifecycle.
How they differ from AI writing assistants and standard SEO platforms
AI writing assistants (the category most content marketers have already worked with) are tools that accelerate a human-led process. A strategist identifies a gap, writes a brief, uses the tool to generate a draft, edits it, and publishes it. The human makes every consequential decision. The tool handles the word production.
Standard SEO platforms surface data - keyword volumes, ranking positions, backlink profiles, content audit scores. They flag problems and opportunities but do not act on them.
An AI content agent closes the loop between these two layers. Given access to a site, a keyword universe, competitor data, and publishing infrastructure, it can identify which topical areas have insufficient coverage relative to competitor authority, produce structured content to fill those gaps, optimize internal linking to concentrate authority, schedule publication, and feed performance data back into the next planning cycle. The human defines the strategic parameters and reviews the output. The agent handles the operational chain between those two endpoints.
The distinction matters because the ranking mechanisms that agents can influence are directly tied to this operational scope. A tool that only drafts cannot build topical authority at scale. A tool that only audits cannot act on its own findings. The combination of perception, decision, and action across the full cycle is what separates agents from their predecessors.
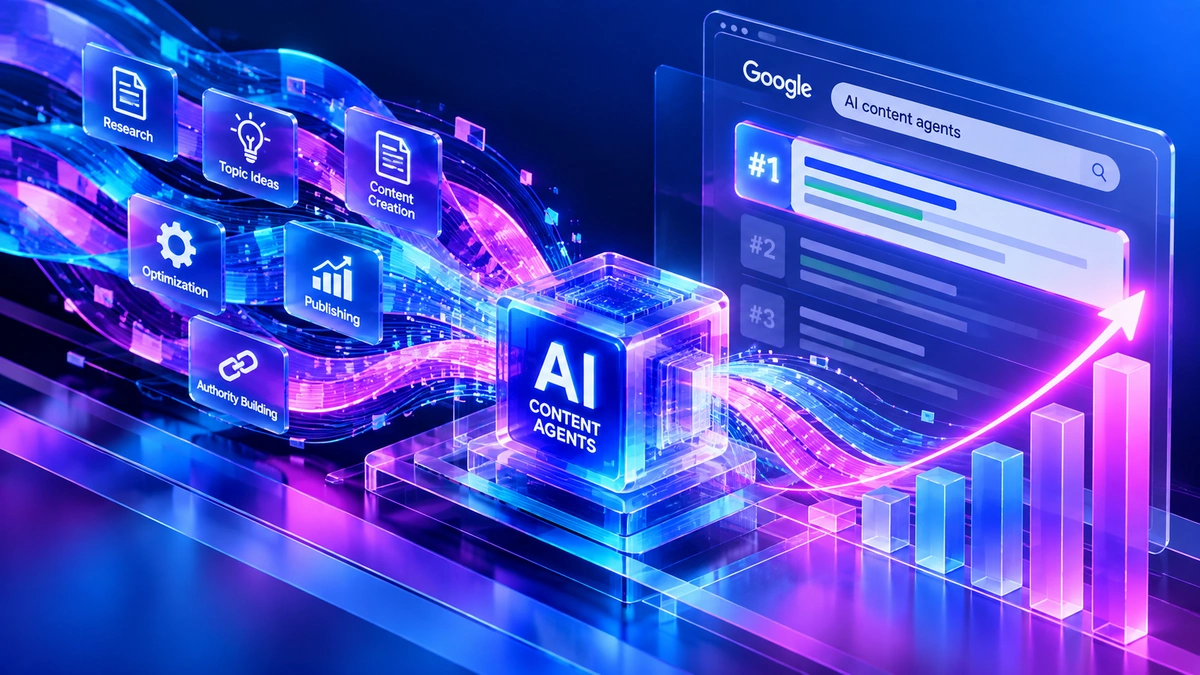
The autonomous loop - research, brief, draft, publish, track
The agentic workflow runs in six connected phases.
First, the agent audits the site's existing content and maps it against the full keyword and entity universe for the domain's target topics. It identifies gaps. Subtopics with no coverage, questions with thin coverage, entities mentioned but never explained, and competitor pages holding positions the site does not contest.
Second, it generates a structured content brief for each identified gap, including target entities, required factual claims, internal linking recommendations, and format specifications matched to the dominant intent pattern for that query.
Third, it produces a draft built to the brief. In well-configured systems, this includes front-loaded direct answers, factual density in the body, and machine-readable structure (schema markup, clear heading hierarchy, named entities consistently applied).
Fourth, the draft enters a scoring and review stage. Better systems score drafts against quality criteria before routing them to human review. The human review gate is not optional in a responsible operation, for reasons the failure-modes section covers in detail.
Fifth, approved content is published with technical optimizations applied. Schema, canonical tags, internal links inserted, and in forward-looking deployments, an updated llms.txt file to signal LLM crawlers.
Sixth, the agent monitors ranking movement, AI citation appearances, organic traffic, and engagement signals, feeding those results back into the next planning cycle to prioritize the next set of gaps.
Why Search Rankings Changed and Why Agents Are the Response
For most of search's history, "ranking" meant one thing. Position in a list of ten blue links on a results page. Content strategy could reasonably optimize for a single surface with a reasonably stable set of signals. That environment no longer exists in the same form.
The rise of AI Overviews, AI Mode, and generative answer engines
Google AI Overviews now appear above traditional results for a substantial portion of informational queries. Google's AI Mode takes this further, replacing the blue-link interface entirely for certain query patterns with a synthesized answer that cites sources rather than listing them as equals. Beyond Google, Perplexity has built a significant user base around AI-generated answer synthesis, and ChatGPT's search integration means that OpenAI's systems are now actively crawling and citing web content through GPTBot and OAI-SearchBot.
Research into how AI-powered search interfaces diverge from traditional ranked results documents a pattern that practitioners are experiencing firsthand. The pages cited inside AI-generated answers do not reliably correspond to the pages ranking at the top of classical results. The citation logic operating inside generative answer engines weights different signals from the ones that determine blue-link position. Optimizing for one surface does not automatically optimize for the other.
ClaudeBot (Anthropic's crawler) and PerplexityBot have joined GPTBot in routinely indexing web content for AI answer generation. Each of these systems evaluates source credibility through its own weighting, but they share a preference for content that is factually precise, clearly attributed, structurally readable, and topically authoritative.
The practical implication is that content strategy now requires satisfying two distinct ranking systems simultaneously. AI content agents are the response to that operational demand because they can be configured to optimize for both surfaces within the same content production cycle, rather than requiring separate workflows for each.
Why the old publish-and-pray model broke down
The publish-and-pray approach (produce content, submit it to Google, wait for rankings to appear) relied on a relatively predictable signal environment - keyword relevance, backlinks, page speed, structured data. If you covered a topic adequately and earned some authority, you ranked.
Three conditions have degraded this approach. First, content volume across the web has increased significantly, raising the baseline for "adequate" coverage on any given topic. Second, AI-generated answer surfaces mean that even ranking well in classical results does not guarantee visibility if the AI surface is pulling users away before they reach the blue links. Third, Google's quality enforcement has sharpened its distinction between content that demonstrates genuine expertise and content that covers a topic superficially at scale.
The old model also assumed a relatively slow content cycle. A competitor publishes a strong piece, you notice it ranking, you write a response over the following weeks, and you compete for the same position. AI content agents operating at scale can close content gaps in hours rather than weeks, which changes the competitive dynamics of informational content categories entirely. The sites running agents are not waiting for a human strategist to notice the gap and commission a brief.
The Four Ranking Surfaces Agents Must Target
Understanding the 2026 ranking environment requires accepting that a single piece of content now needs to perform across multiple distinct surfaces, each with different inclusion criteria. A well-configured AI content agent optimizes for all four within the same production cycle.
Classical Google blue-link results
Traditional ranked results still drive the majority of click-through traffic for most sites. The signals that determine position here are well-documented. Topical authority (the depth and breadth of coverage within a domain's subject area), backlink authority, page experience, structured data, content quality as evaluated by E-E-A-T criteria, and freshness for time-sensitive topics.
AI content agents improve performance on this surface primarily by building topical authority at scale. A site with comprehensive, semantically coherent coverage of every meaningful subtopic and entity within its domain signals to Google's classifiers that it is a genuine authority on the subject. Agents close the gaps in that coverage systematically, which produces measurable ranking improvements on long-tail and mid-tail queries where the gap between the site's existing coverage and the full topical universe is largest.
Google AI Overviews and AI Mode citations
AI Overviews appear at the top of results for a large share of informational queries and are generated by Google's own AI systems synthesizing information from indexed content. Being cited inside an AI Overview is now a meaningful visibility objective independent of classical ranking position.
The inclusion signals for AI Overviews overlap with but differ from classical ranking signals. Content that is cited tends to be factually precise, directly answers a specific question near the top of the page, uses clear entity references that match the query, and comes from a domain with established topical authority in the relevant area. Buried answers, vague entity references, and thin factual density reduce the probability of citation even from a page that ranks well classically.
A 2026 audit of AI-powered generative search behavior and how citations diverge from classical rankings confirmed that being cited in AI Overviews and holding a high classical ranking are related but not equivalent conditions. Pages with moderate classical rankings but high factual density and direct question-answer structure were cited in AI Overviews at higher rates than higher-ranking pages with more general coverage.
Agents configured for AI Overview optimization produce content with front-loaded direct answers, high entity specificity, and clear factual claims that are easy for Google's synthesis layer to extract and attribute.
ChatGPT and Perplexity answer citations
ChatGPT's search integration and Perplexity both pull from indexed web content to generate answers, and both name their sources. For many informational queries, appearing as a cited source in these interfaces now drives traffic and brand authority independently of any Google ranking.
The crawlers involved are GPTBot and OAI-SearchBot for OpenAI's systems, and PerplexityBot for Perplexity. These systems favor content that is factually dense, clearly structured, and comes from domains that have established a reputation for accuracy in the relevant topical area. Content that is generically written, poorly attributed, or structurally ambiguous is less likely to be cited.
Generative Engine Optimization (GEO) has emerged as the discipline specifically concerned with earning citations in AI-generated answers. GEO differs from classical SEO in that it focuses less on keyword positioning and more on the clarity, precision, and extractability of factual claims. An agent applying GEO principles produces content where the answer to a specific question can be identified, extracted, and attributed by an AI system reliably, without ambiguity about what the claim is or who is making it.
Large Language Model Optimization (LLMO) extends this further, specifically addressing how content is structured to be used as training or inference context by large language model systems. Machine-readable structure, consistent entity naming, and factually precise claims that can be evaluated for accuracy are the core characteristics LLMO targets.
Third-party authority signals that feed all surfaces
All four ranking surfaces are influenced by a domain's overall authority as established through backlinks, brand mentions, entity associations in knowledge graphs, and the consistency with which the domain is cited by other authoritative sources. AI content agents that build topical depth also tend to attract natural links to individual pages within the coverage cluster, which strengthens domain authority and feeds back into classical rankings, AI Overview inclusion, and LLM citation probability simultaneously.
The agents that produce the strongest multi-surface results do not treat these surfaces as separate objectives. They produce content that satisfies classical ranking signals, AI Overview citation criteria, LLM citation structure, and authority-building requirements within the same production output, guided by a brief that specifies requirements for all four simultaneously.
How AI Content Agents Improve Rankings - The Core Mechanisms
The mechanisms by which AI content agents move rankings are specific and conditional. Understanding each one, including the conditions under which it works and the conditions under which it does not, is what separates a realistic deployment plan from a vendor-pitch expectation.
Intent modeling and topical authority building
Topical authority is the degree to which a domain demonstrates comprehensive, accurate, and interlinked coverage of a subject area. Google's classifiers and AI-powered ranking systems both evaluate topical authority, though they weight its components differently. Classical ranking rewards depth of individual pages and coherence of internal linking. AI answer systems reward the domain's overall reputation as an accurate source in the relevant area.
AI content agents build topical authority by systematically identifying the full entity and question space within a domain's target topics and producing content to fill the gaps. A site covering project management software, for example, might have strong coverage of core product category pages but thin coverage of the specific workflow problems those tools solve, the industries that use them, and the comparative questions buyers ask during evaluation. An agent mapping the entity space identifies these gaps, prioritizes them by search volume and citation opportunity, and produces content to close them.
The resulting authority signal is more than volume. It is semantic coherence. The internal links between pieces connect related entities, the vocabulary used across the cluster is consistent, and the factual claims in different pieces do not contradict each other. Semantic coherence is what distinguishes authority-building content production from content-at-scale that creates more noise than signal.
Intent modeling is what makes this possible at scale. An agent that classifies query intent correctly (informational versus commercial versus navigational) produces content with the right structure for each intent type. Informational queries need direct answers and factual depth. Commercial queries need comparison structure and decision support. An agent producing the same format for every content type produces content that performs poorly across the board despite high volume.
Factual density and machine-readable structure
Research into how AI generative tools affect content performance in low-cost marketing channels points to a consistent pattern. AI-generated content that performs well combines factual precision with structural clarity. Vague general statements, unsupported assertions, and rambling explanations reduce both classical ranking signals and AI answer citation probability.
Factual density means that each paragraph contains specific, verifiable claims rather than general statements. "Project management software reduces meeting time" is a general claim. "Teams using project management tools that centralize task status reporting consistently report fewer status-update meetings because the information is available asynchronously" is factually dense enough for an AI system to extract and attribute.
Machine-readable structure means clear heading hierarchy, consistent entity naming throughout a document, schema markup that labels the type of content (FAQ, HowTo, Article) and its key components, and internal link anchor text that accurately describes the linked page rather than using generic labels.
Well-configured AI content agents apply both of these at the brief stage, specifying required factual claims, entity references, and structural components before drafting begins, so the output is built for citation rather than retrofitted for it.
Gap diagnosis and citation opportunity targeting
One of the most direct ranking mechanisms an AI content agent operates through is gap closure. When a domain has no content covering a specific question or entity that is generating significant search volume, it has zero chance of ranking for that query or being cited in AI answers about it. Closing the gap is the minimum requirement for visibility.
Agents perform gap diagnosis by mapping the full keyword and entity universe for a domain's topics against the site's existing content inventory. The output is a prioritized list of uncovered or undercovered gaps ranked by opportunity. Search volume, competitor coverage, citation frequency in AI answers, and the domain's existing authority in the relevant area.
Citation opportunity targeting is a more specific version of this. By analyzing which pages in a domain's topic area are already being cited in AI Overviews and ChatGPT answers, an agent can identify the content patterns that earn citation (structure, factual type, entity specificity) and replicate those patterns in new content targeting adjacent gaps. This is not plagiarism. The pattern being replicated is structural (direct answer at the top, specific factual claims in the body, clear entity attribution) rather than substantive.
Technical signals - llms.txt, schema markup, and crawler access
The technical layer of AI content optimization is one of the most underserved areas in most SEO strategies.
Schema markup signals the type of content and its components to both classical crawlers and AI crawlers. FAQ schema makes question-and-answer pairs extractable. HowTo schema makes process steps parseable. Article schema with author and date metadata strengthens E-E-A-T signals. Agents that generate and maintain schema markup as part of the publishing step close a gap that many content operations leave open because it requires technical implementation alongside content production.
llms.txt is an emerging standard (analogous to robots.txt but directed at LLM crawlers) that signals which pages on a site are high-quality, trustworthy, and appropriate for AI indexing. It is not yet a universal standard, but Anthropic, Perplexity, and others have indicated support for it. A site with a well-maintained llms.txt that directs LLM crawlers to its strongest, most authoritative content is more likely to have that content indexed and cited than a site where the crawlers must make their own assessments without guidance. AI content agents in more sophisticated deployments generate and update llms.txt as part of the technical optimization step.
Crawler access is a prerequisite that is surprisingly often misconfigured. GPTBot, ClaudeBot, PerplexityBot, and OAI-SearchBot all need access to pages for those pages to be indexed for AI answer generation. A robots.txt that blocks these crawlers (often set during earlier periods when AI crawlers were unwanted) silently eliminates the site from AI answer inclusion. Agents with technical access to site configuration can audit and correct this.
Staying Inside Google Policy - Helpful Content vs. Scaled Abuse
The most common objection to AI content agents from experienced SEOs is a legitimate one. Doesn't producing content at scale with AI trigger Google's quality penalties? The honest answer requires a precise account of what Google's documentation actually says, what it penalizes, and how a well-configured agent operates relative to that boundary.
What Google's documentation actually rewards in 2026
Google's Helpful Content system, now integrated into its core ranking algorithm, evaluates content against questions centered on the Google Helpful Content Guidelines. Does this content demonstrate first-hand expertise and depth of knowledge? Does it provide a satisfying answer that leaves the reader with what they came for? Was it produced primarily to earn search rankings, or primarily to help the reader?
These are not questions about how content was produced. They are questions about the quality and purpose of the output. Google's documentation explicitly states that the method of production (including AI) is not the determining factor. Content that demonstrates genuine expertise and provides real value meets the standard regardless of how it was made. Content that is thin, generic, and produced primarily for search manipulation fails the standard regardless of how it was made.
This is the honest framing. AI content agents that are configured to produce factually dense, topically coherent, expertly structured content that genuinely addresses reader questions can produce output that meets Google's quality standards. AI content agents that are configured to maximize volume without quality controls produce output that fails those standards.
What triggers a scaled content abuse penalty
Google's scaled content abuse policy targets a specific pattern. Generating large volumes of content with little original value, primarily for the purpose of manipulating search rankings. The relevant characteristics are low information density, high similarity across pieces (templated structure with substituted keywords), no demonstrable first-hand expertise, and a production pattern inconsistent with genuine editorial intent.
A site that publishes 200 nearly identical articles about regional variations of a service, each with the same structure and only the city name changed, is exhibiting scaled content abuse. A site that publishes 200 articles each covering a distinct question about a complex topic, with different structures, specific factual claims, and coherent internal linking, is exhibiting topical authority building. The volume is similar. The quality pattern is entirely different.
The risk is real. Research into how AI tools are applied in content production contexts notes that the speed advantage AI tools provide creates a temptation to maximize volume rather than quality. Organizations that optimize for output quantity without equivalent investment in quality controls are the ones most likely to encounter scaled content abuse penalties.
How a well-configured agent avoids the boundary
A well-configured AI content agent avoids the scaled content abuse boundary through three mechanisms.
First, it operates from a quality-first brief rather than a volume-first directive. Each content brief specifies required factual claims, entity coverage, structural requirements, and minimum information-density targets. The agent produces to the brief, not to a word-count or article-count target.
Second, it incorporates a human review gate before publication. The agent scores drafts against quality criteria and routes those that meet the threshold to human review. The human reviewer evaluates originality, factual accuracy, and genuine helpfulness before approving publication. This gate is not cosmetic. It catches the failure modes that agents produce most frequently (factual errors, entity inconsistencies, generic phrasing that sounds plausible but says nothing specific).
Third, it monitors post-publication quality signals and feeds them back into configuration. If agent-produced content in a particular format or on a particular topic type is showing low engagement signals, high bounce rates, or declining rankings, the agent's configuration is adjusted before the pattern proliferates across the content cluster.
AI Content Agents vs. Traditional SEO Tools - A Direct Comparison
The distinction between AI content agents, traditional SEO platforms, and basic AI writing tools is clearest when viewed across the dimensions that actually affect ranking outcomes. The following comparison focuses on the operational characteristics that determine what each approach can and cannot accomplish.
| Dimension | AI Writing Tools | Traditional SEO Platforms | AI Content Agents |
|---|---|---|---|
| Autonomy level | Human-initiated, tool-assisted | Human-initiated, data surfaced | Autonomous multi-step loop |
| Surface coverage | Single piece, no surface optimization | Classical rankings only | Classical + AI Overviews + LLM citation surfaces |
| Topical authority building | Piece-by-piece, no gap mapping | Audits gaps, human acts | Gap maps and fills autonomously |
| Content freshness | Manual refresh required | Flags staleness, no action | Schedules and executes refreshes |
| Schema and technical optimization | Requires separate workflow | Platform-specific, limited | Integrated into publishing step |
| Quality control | Fully human-dependent | N/A for content quality | Scored before human review |
| llms.txt management | Not supported | Not applicable | Generates and maintains |
| Internal linking | Manual or no integration | Suggests links, no execution | Inserts links at publication |
| Policy risk | Low volume, low risk | Low volume, low risk | High volume requires quality gates |
| ROI timeline | Immediate output, slow ranking gain | Data insight, no direct ranking gain | 3-6 months for topical gain. AI citations faster |
The table summarizes the practical consequence. Traditional tools and basic AI writers handle different parts of the problem without connecting them. An AI content agent connects gap identification, production, optimization, publication, and monitoring into a single operational cycle. That integration is where the ranking benefit comes from, not from any individual capability in isolation.
Building an Agentic Content Workflow from Day One
Setting up an AI content agent workflow correctly from the start prevents the failure modes that produce poor results and, in worst cases, quality penalties. The following steps reflect what a responsible deployment looks like.
Step 1 - Keyword and citation gap discovery
Begin by establishing the full topical map for the domain's subject area. This means inventorying all existing content (URLs, topics, entities covered, current rankings), mapping it against the full keyword and entity universe for the domain's subject area, and identifying the gaps. Prioritize gaps by opportunity. Search volume, competitor coverage strength, and presence or absence of that topic in AI answer surfaces. A gap that appears frequently in AI Overview answers but is uncovered on your site is a high-priority citation opportunity, not just a traffic opportunity.
At this stage, also audit which LLM crawlers have access to the site. Check robots.txt for any GPTBot, ClaudeBot, or PerplexityBot blocks. Unintended blocks are common on sites that adopted crawler-blocking practices before AI search indexing was a meaningful concern. Correcting them before producing new content ensures the content can be indexed for AI answer surfaces.
Step 2 - Brief generation with intent and entity mapping
For each prioritized gap, generate a structured content brief. The brief specifies the primary query and its intent type, the key entities that must be covered and the relationships between them, the required factual claims (not just topics but specific information that must appear in the content), the structural requirements (direct answer at top, FAQ section, schema type), and internal linking targets.
Entity mapping within the brief is what produces semantic coherence at scale. When every brief in a topical cluster specifies the same core entities and their relationships consistently, the resulting content cluster has a coherent knowledge structure rather than a collection of loosely related articles that confuse crawlers about what the site's authoritative territory actually is.
Step 3 - Drafting with front-loaded answers and factual density
The agent produces a draft from the brief. The draft should open with a direct answer to the primary query within the first paragraph. This is not a stylistic preference. It is a citation requirement. AI systems extracting content for Overviews and answer generation need the answer to be findable at the top of the page.
The body of the draft should develop factual depth in each section, use consistent entity names throughout, and build toward the internal link targets specified in the brief. The agent should apply schema markup at the drafting stage rather than retrofitting it after the fact.
Step 4 - Scoring, editing, and human review
Before any agent-produced draft reaches publication, it should be scored against quality criteria. Factual density, entity consistency, information gain relative to existing top-ranking content, structural correctness, and absence of the generic phrasing patterns that produce low-engagement content. Drafts below threshold are returned for revision or flagged for deeper human editing.
Human review at this stage focuses on factual accuracy (AI agents produce plausible-sounding errors that pass automated scoring), brand voice consistency, and any claims in regulated or sensitive areas that require expert verification. In YMYL categories (medical, financial, legal), human expert review is not optional regardless of the agent's quality score.
The review gate is where the agent's speed advantage meets the quality discipline that determines whether that speed produces rankings or problems. Organizations that eliminate this gate to maximize throughput are the ones most likely to encounter quality penalties at scale.
Step 5 - Publishing and technical optimization
At publication, the agent applies the technical layer. Schema markup is inserted and validated. Internal links are placed at the anchor text specified in the brief. Canonical tags are set correctly. For sites using llms.txt, the file is updated to include the new page with appropriate priority signals. Meta descriptions are generated from the direct answer in the opening paragraph, maximizing the probability that the meta description is useful to both human searchers and crawler systems.
Crawl submission for the new URL ensures timely indexing by both Google's classical crawlers and the LLM crawlers for AI answer generation.
Step 6 - Tracking visibility across classical and AI surfaces
Monitoring for agent-produced content must cover both ranking surfaces. Classical rankings are tracked through standard position monitoring for target queries. AI Overview appearances are tracked by querying the target questions in Google and recording whether the domain's content appears in the Overview, and if so, where. ChatGPT and Perplexity citation tracking requires querying those systems with target questions and recording whether the domain's pages appear as cited sources.
Content performance attribution feeds these signals back into the gap discovery phase. Pages earning AI citations but low classical rankings signal a structure that excels on AI surfaces. Pages ranking well classically but absent from AI surfaces signal content that needs structural adjustment for AI optimization. This distinction is what closes the loop and makes the agent's next planning cycle smarter than the previous one.
What Realistic ROI and Timeline Look Like
The honest account of AI content agent performance timelines differs meaningfully from what vendor pitches suggest. Understanding the realistic pattern prevents misattribution of early results as confirmation of success and later results as evidence of failure.
AI citation gains (appearances in ChatGPT, Perplexity, and Google AI Overviews) tend to arrive before classical ranking gains. The reason is structural. AI answer systems can surface a page as a citation source relatively quickly after indexing if the page's content structure meets citation criteria. Classical ranking improvements, particularly for mid-tail and head terms, depend on accumulated authority signals (internal linking, backlinks, engagement data) that take longer to build.
A realistic timeline for a site deploying AI content agents responsibly (with quality gates and strategic gap targeting) looks roughly like this. In the first four to eight weeks, newly published content begins indexing and appearing in AI answer citations for specific question queries. Classical rankings for new pages may not appear yet for competitive terms but appear quickly for long-tail queries with low competition. Between months two and four, topical authority signals begin to consolidate as internal linking density increases and the content cluster fills out. Classical rankings improve for mid-tail queries. AI citation frequency increases as the domain's authority in the topic area becomes established across AI systems. Between months four and six, measurable classical ranking improvements appear for target keyword groups if the topical authority building has been systematic and the content quality consistent. Core head-term competitive positions rarely shift in this window without additional authority signals (backlinks, brand signals) beyond content alone.
The metrics worth tracking are AI citation frequency (by surface), classical ranking position movement for target keyword groups, organic click-through by content cluster, and content engagement signals (time on page, scroll depth, return visits). Tracking only classical ranking positions in this environment produces a systematically incomplete picture of the ROI.
One honest limitation deserves naming directly. AI content agents are not a substitute for domain authority earned through backlinks, brand recognition, and sustained publishing history. A new site deploying agents will see faster long-tail coverage gains than an established competitor site deploying the same tools, because the marginal topical coverage improvement is larger. But a new site will not outrank an established authority site on competitive head terms through content production alone, regardless of the tools used.
The Human Role in an AI-Agent Content Operation
The replacement question is real and reasonable. If an agent can research, brief, draft, optimize, publish, and monitor content autonomously, what does the content team do?
The honest answer is that the human role shifts rather than shrinks, and in certain dimensions it becomes more consequential, not less. The quality of an AI content agent's output is directly determined by the quality of its configuration, the precision of its strategic direction, and the rigor of the review gates placed between production and publication. All three of these are human responsibilities.
Strategic direction involves decisions that agents cannot make well. Which topics are worth the domain's authority investment, which angles differentiate the site from competitors, which factual claims require domain expertise to evaluate, and which content types represent the brand's genuine position rather than just coverage for coverage's sake. An agent directed to cover everything produces a generalist site. An agent directed by a strategist who understands where the domain has genuine depth produces an authority site.
Editorial judgment is the review-gate function. The agent scores and filters, but the human editor is the one evaluating whether a factual claim is actually accurate (not just plausible-sounding), whether a piece of content advances the brand's genuine perspective or just restates industry consensus, and whether the tone and depth are consistent with the site's published standards. This judgment cannot be automated without producing the failure modes that damage rankings and user trust simultaneously.
Brand voice and original insight are the hardest things for agents to replicate at quality. Content that demonstrates genuine expertise signal, the kind that earns both user trust and E-E-A-T credit in ranking systems, contains specific observations that reflect actual experience, perspectives that go beyond consensus restatement, and examples drawn from real operational knowledge. The human contributors to an agent-augmented content operation are the source of that material. They provide the intellectual content that the agent structures, scales, and optimizes.
The practical implication for team design. AI content agents do not reduce the need for strategic and editorial talent. They reduce the need for production labor (the hours spent drafting, formatting, interlinking, and scheduling) and redirect human attention toward the higher-leverage activities that determine whether the production output is worth ranking.
Choosing the Right AI Content Agent for Your Operation
The market uses "AI content agent" to describe tools with significantly different actual capabilities. Evaluating tools against the following criteria separates genuine agents from more basic automation.
The first criterion is autonomous gap diagnosis. A real agent identifies content gaps and prioritizes them without requiring a human to specify what to look for. Tools that require a human to input target keywords before they can act are not agents in the operational sense. They are assistants. Evaluate whether the tool can survey a domain, map its topical coverage, and produce a prioritized gap list independently.
The second criterion is multi-surface optimization. The brief-generation capability should produce specifications that include AI Overview citation structure, LLM-readable formatting, and classical ranking requirements within the same output. A tool that optimizes only for one surface will underperform in the 2026 multi-surface environment regardless of its other capabilities.
The third criterion is technical integration. Does the tool publish directly to the site's CMS with schema markup applied? Does it manage internal linking automatically? Does it interact with the site's technical infrastructure (robots.txt, llms.txt, sitemap) or only produce content documents that require separate technical handling?
The fourth criterion is quality scoring and routing. A responsible agent evaluates its own output before routing to human review. Tools with no quality scoring mechanism require the human reviewer to catch every problem, which defeats the purpose of the autonomous loop at scale.
The fifth criterion is closed-loop tracking. The tool should monitor the performance of published content and feed that data back into gap discovery and brief generation. Without this feedback loop, the agent is not actually autonomous in any meaningful sense. It produces content without knowing whether it performs, which prevents the iterative improvement that distinguishes agent-level operations from bulk content production.
The sixth criterion, relevant for organizations in sensitive categories, is the quality of its human review workflow. How does the tool route flagged content to appropriate reviewers? How does it handle YMYL content types? A tool with no concept of content sensitivity is not appropriate for medical, legal, or financial publishers regardless of its other capabilities.
Where AI Content Agents and Search Rankings Are Headed
AI content agents improve search rankings in 2026 through specific, well-defined mechanisms. Topical authority building at scale, multi-surface content optimization, systematic gap closure, technical signal management, and closed-loop performance tracking. These mechanisms produce measurable ranking improvements under specific conditions (strategic deployment, quality gates in place, human editorial oversight maintained) and produce poor or counterproductive results when those conditions are absent.
The practitioner's dilemma that opened this discussion, the gap between vendor claims and verifiable outcomes, resolves when the question is reframed. The right question is not whether AI content agents improve rankings. The evidence is sufficient to say they do, under defined conditions. The right questions are whether your deployment satisfies those conditions, whether your site is in a content situation where agent-driven topical coverage building produces meaningful gains, and whether your human editorial infrastructure can maintain quality at the velocity agents make possible.
The near-future direction is toward tighter integration between content agents and the ranking systems they are optimizing for. As AI search surfaces stabilize and their citation logic becomes better understood through research like the audit of how citations diverge from rankings in AI-powered search interfaces, agent configurations will become more precisely targeted to the specific signals each surface rewards. The sites that benefit most will be the ones that have already built the operational infrastructure (agent configuration, editorial workflows, multi-surface tracking) while the competitive field is still learning what the surfaces require.
The next step for any organization evaluating this approach is not to choose a tool. It is to audit the current content state - topical gaps, existing authority, editorial capacity, and YMYL sensitivity. The audit determines the deployment model that fits the situation, which determines the tool requirements, which determines the evaluation criteria. Starting with tool selection and working backward produces the mismatch between capability and need that most early AI agent deployments have encountered.
Frequently Asked Questions
What is the difference between an AI content agent and a standard AI writing tool?
An AI writing tool accelerates a human-led process. A human identifies the topic, writes a brief, uses the tool to draft, edits the output, and publishes manually. An AI content agent operates autonomously across the full content lifecycle. It identifies content gaps, generates its own briefs, drafts to those briefs, applies technical optimization, publishes, and monitors performance without requiring human initiation at each step. The human sets strategic parameters and reviews output, but does not direct each individual task. The operational difference is significant. Agents can close topical gaps at a pace and scale that human-led processes cannot match, which is what produces the topical authority improvements that move rankings.
Do AI content agents help with Google AI Overviews specifically?
Yes, when configured correctly. Content that earns citations inside Google AI Overviews tends to share specific characteristics. A direct answer to the query within the first paragraph, high factual density in the body, clear entity references that match the query language, and schema markup that helps Google's synthesis layer identify the content type and key claims. AI content agents that generate briefs specifying these structural requirements produce output that performs better as AI Overview citation candidates than content produced without these specifications. That said, there is no guarantee of inclusion. Google's AI Overview selection also weighs domain authority and the overall quality of the site's content, which agents can improve over time but cannot establish instantly.
How do AI agents handle Google's helpful content guidelines without triggering penalties?
The helpful content guidelines evaluate output quality and intent, not production method. An AI content agent avoids penalties by producing content that demonstrates genuine information value (factual depth, specific claims, real answers to real questions) rather than content optimized primarily for keyword manipulation. The practical safeguards are a quality-first brief that specifies information requirements rather than word-count targets, a scoring mechanism that evaluates drafts before routing to human review, and a human review gate that catches factual errors and generic phrasing before publication. The scaled content abuse penalty specifically targets high-volume production of low-value, templated content. An agent producing topically diverse, factually dense, structurally varied content across a coherent subject area does not exhibit that pattern.
What is llms.txt and does my site need one?
llms.txt is a text file placed in a site's root directory that signals to LLM crawlers (GPTBot, ClaudeBot, PerplexityBot) which pages are high-quality, trustworthy, and appropriate for AI indexing. It functions analogously to robots.txt but is directed at AI crawlers rather than classical search crawlers. The standard is not yet universally adopted or required, but Anthropic and Perplexity have indicated they support it, and it represents a forward-looking technical signal for AI answer surface inclusion. Sites in competitive informational categories where AI citation is a meaningful traffic objective should consider implementing it. AI content agents in more sophisticated configurations can generate and maintain llms.txt as part of their technical optimization workflow.
How long before AI content agents produce measurable ranking improvements?
AI citation appearances (in ChatGPT, Perplexity, and Google AI Overviews) tend to appear within the first four to eight weeks for pages with strong citation structure, because AI systems can surface newly indexed pages relatively quickly if the content structure meets their criteria. Classical ranking improvements for long-tail queries follow in the first two to four months as pages index and accumulate initial engagement signals. Meaningful classical ranking improvements for mid-tail competitive queries typically require four to six months of systematic topical authority building. Core competitive head-term improvements depend on additional authority signals beyond content production and rarely appear within the first year of an agent deployment. Organizations that measure only classical rankings in the first few months will underestimate the value being generated in AI citation surfaces during that period.
Will AI content agents replace content marketing teams?
Not in their current form, and the direction of development suggests specialization rather than replacement. The aspects of content marketing that agents handle well are operational - gap identification, briefing, drafting, technical optimization, internal linking, and performance monitoring. The aspects that remain human-dependent are strategic. Determining which topics represent genuine authority opportunities versus commoditized coverage, contributing first-hand expertise and original perspective, maintaining brand voice consistency, evaluating factual accuracy in areas requiring domain knowledge, and making editorial judgments about what the organization should be known for. Teams that deploy agents effectively redirect human talent toward these higher-leverage activities rather than reducing headcount. The organizations that have struggled with agent deployments are often the ones that eliminated editorial oversight to maximize throughput and then encountered quality degradation at scale.
What is the difference between SEO, AEO, GEO, and LLMO in 2026?
These four terms describe optimization objectives for different ranking surfaces. Classical SEO (Search Engine Optimization) targets traditional blue-link rankings in Google and other search engines through the well-established signals of topical authority, backlinks, page experience, and content quality. Answer Engine Optimization (AEO) targets direct-answer placements. Featured snippets, People Also Ask boxes, and similar structured answer formats within classical search results. Generative Engine Optimization (GEO) targets AI-generated answer surfaces specifically - Google AI Overviews, Perplexity answers, and ChatGPT search results. It focuses on the structural and factual characteristics that make content extractable and citable by AI synthesis systems. Large Language Model Optimization (LLMO) addresses how content is structured to be used by LLM systems more broadly, including as inference context, with an emphasis on machine-readable structure, consistent entity naming, and factual precision that AI systems can evaluate and attribute. A well-configured AI content agent optimizes for all four within the same content production cycle, which is a meaningful capability advantage over tools or workflows that address only one surface.